Rahbar: A Voice-First Urdu–English AI Tutor for Pakistan
A voice-first tutor for learners who mix Urdu and English when they speak. Rahbar answers from the course material in the same Urdu–English mix, highlights the matching part on a 3D diagram, and ends each unit with a quiz and a spoken viva. Demonstrated on Auto Electrician education.
Status
In progress
Programme
BS Computer Science
School
SEECS, NUST
Curriculum
TEVTA Punjab Auto Electrician
01Team
ES
Esha Shabbir
Student · CMS 453839
MH
Muhammad Hunain Ashraf
Student · CMS 463395
AA
Arfa Abdul Nasir
Student · CMS 456634
Dr. Junaid Younas
Advisor
Dr. Muhammad Moazam Fraz
Co-Advisor
02Abstract
Rahbar is a voice-first AI tutor for Pakistani learners who mix Urdu and English when they speak. A learner listens to a spoken lesson and can interrupt with a question at any time. Rahbar answers from the course material in the same Urdu–English mix and highlights the related part on a 3D diagram. Each unit ends with a quiz and a spoken viva, and questions can also be sent by text or voice note on WhatsApp.
It is being built on the TEVTA Punjab Auto Electrician curriculum; the voice engine itself is not tied to one subject.
11.9%
word error rate from the tutor’s default speech recognition
88.5%
English technical terms preserved in transcription
Pakistani learners often ask technical questions as Urdu sentences full of English terms — for example, asking where relay terminal 85 is connected, with the technical nouns in English inside an Urdu sentence. This code-switching is hard for voice systems built for one language: on the UrduSpeech benchmark, Whisper-large-v3 has a 28.9% word error rate on Urdu but 53.2% on code-switched speech. Outside class, learners only have one-way videos, text platforms that need reading and typing, or general chatbots that may invent specifications.
Problem statement. The team did not find a tool that lets a learner speak a code-switched question and hear a correct, curriculum-based answer. This needs recognition that keeps English terms in English and Urdu in Urdu script; answers drawn only from the course material, declining when it is silent; speech with the technical terms intact; and replies fast enough for conversation. In auto electrical work, around batteries and live circuits, a confident wrong answer can cause harm, so grounding is required.
04Methodology
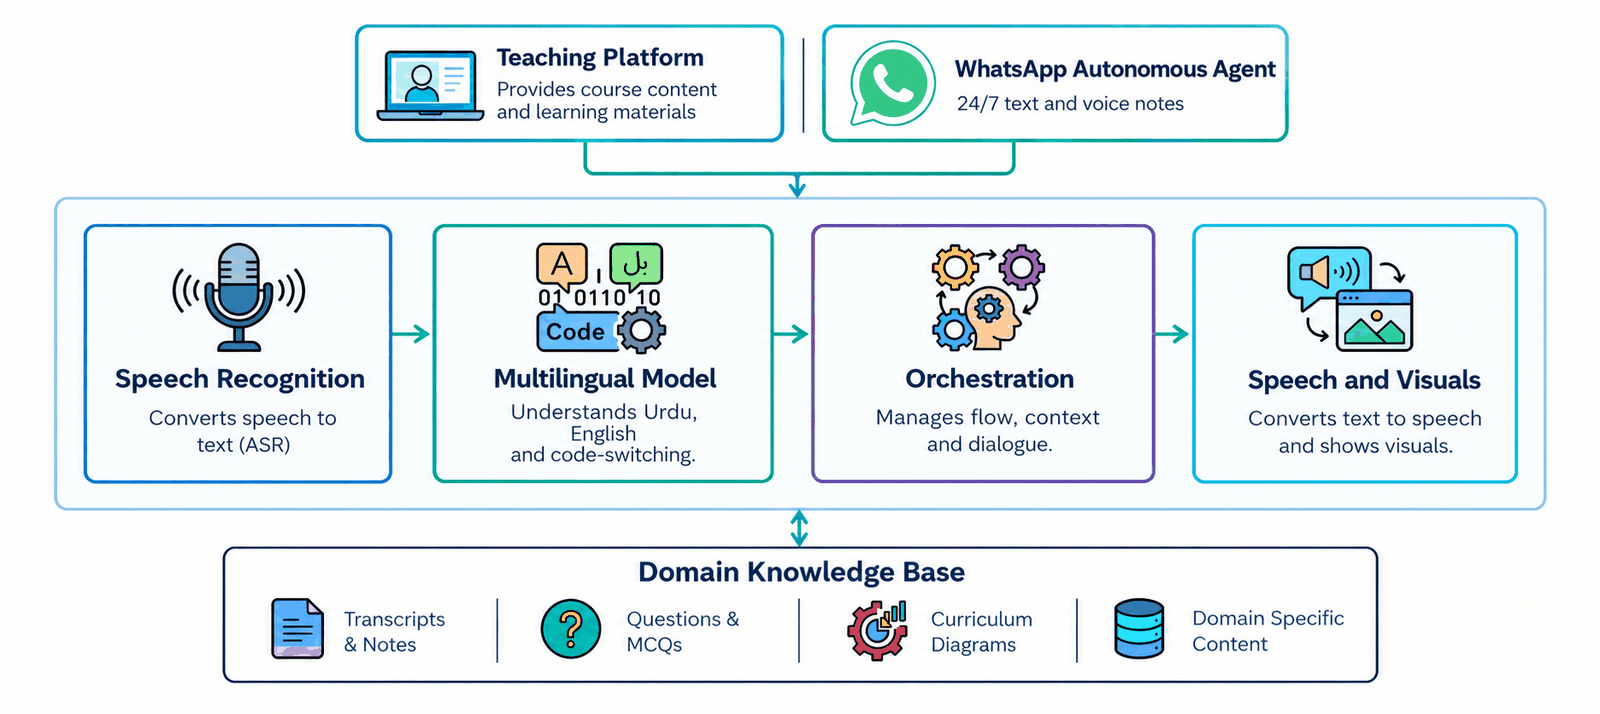
Speech recognition. Voice activity detection lets the learner interrupt at any time. The current default is an open Hindi–English Whisper model plus a rule-based Devanagari-to-Urdu converter; a Whisper-family model is being fine-tuned with LoRA on the 89.4-hour code-switched part of UrduSpeech.
Orthographic contract. One writing rule at every stage: Urdu in Urdu script, English terms in Latin script, numbers and units written out before speech. A normaliser enforces it and logs where each violation happened.
Retrieval. Course passages are tagged by unit and searched with BGE-M3 and BM25, merged by reciprocal rank fusion. Search starts in the learner’s current, pre-cached lesson and falls back to the whole course.
Grounded answering and safety. Qwen3.5-4B answers in mixed Urdu–English, one sentence at a time, only from the retrieved passages.
Speech and visuals. OmniVoice speaks each checked sentence while its part tag highlights the matching part of the 3D diagram.
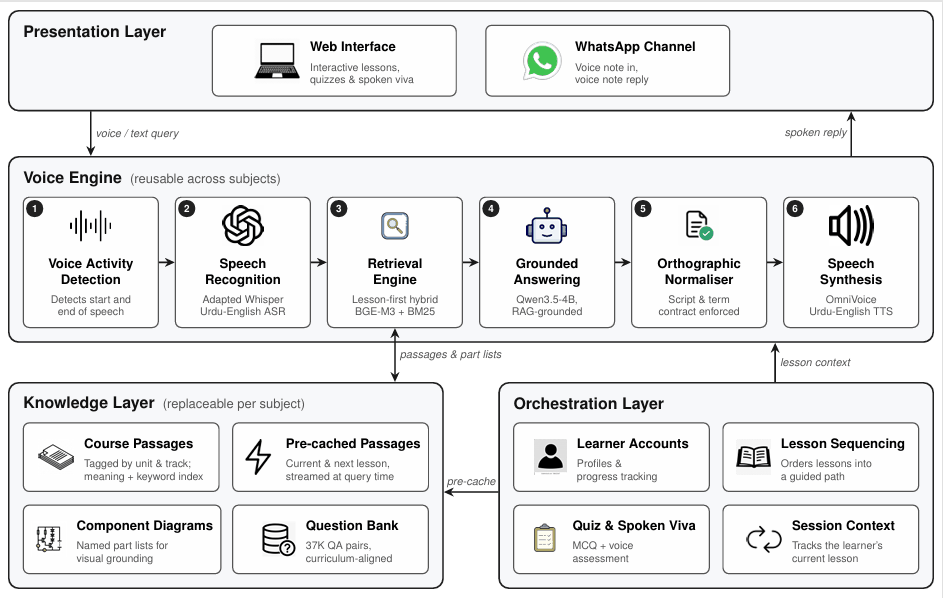
Overview. A question from the web platform or WhatsApp passes through four stages of the voice engine, and every answer is drawn only from the subject’s knowledge base.Detailed architecture. A spoken turn passes through the numbered stages one sentence at a time, so the learner hears the first sentence while the rest is still being generated. Only the knowledge layer changes when Rahbar moves to a new subject.
05Preliminary results
Small in-house tests on free T4 GPUs — 20 code-switched clips and 30 spoken questions from one speaker. These are starting baselines, not general findings.
Speech recognition
Whisper-large-v3 gave 52.3% WER and kept only 5.9% of English words. Urdu fine-tunes gave 26.8–32.5% WER and kept at most 28.2% of English terms. A Hindi–English Whisper kept 91.8% but wrote Urdu in Devanagari; the team’s converter cut its WER from 35.9% to 23.4%. In the tutor test this default gave 11.9% WER, kept 88.5% of terms, and took about 1.3 s per question.
Speech synthesis
Of nine configurations, OmniVoice had the lowest character error rate (0.097) and was the only one to keep English terms in every case.
Answering and retrieval
Across 26 answerable questions, having no course material produced 8 wrong answers. Lesson-first retrieval gave 19 correct and 1 wrong, and found the right lesson for 23 of 26, against 5 of 26 for whole-course search. Translating through English was about twice as slow and invented facts.
Response time
Median time to first audio was about 7.4 s — 3.3 s for the language model, 2.9 s for speech synthesis and 1.3 s for recognition.
3D highlighting
29 of 30 tagged replies pointed to the correct part, and no invalid part reached the screen.
WhatsApp
On a prototype using Meta’s test number, all 8 messages were received and every reply delivered.
06Expected outcomes
Deliverables.
A hosted web tutor with lessons, Q&A, quiz and viva.
A reusable, subject-independent voice engine.
WhatsApp access by text and voice note.
An adapted Urdu–English speech-recognition model and benchmark.
Targets, fixed in advance.
Word error rate at or below 20%, and below every screened model.
At least 90% of English terms kept, and at least 90% compliance with the orthographic contract.
At least 80% of answers correct or partly correct, with zero unsafe answers.
At least 85% correct refusals, and a median time to first audio under 10 s.
Impact. Course-based help outside class hours without reading or typing.
07Sustainable Development Goals
4Quality Education
8Decent Work and Economic Growth
10Reduced Inequalities
08Publications
Nothing published, accepted or under review yet.
Depending on final results, the work may lead to:
A speech-recognition benchmark and model. The team is attempting to fine-tune an open Whisper-family model to beat existing open models on Pakistani Urdu–English speech. A benchmark reporting English-term preservation and script errors alongside word error rate may be publishable either way, as they did not find one for Urdu–English. If the model clearly wins, they may also release it.
Grounded spoken question answering. Early results suggest lesson-first retrieval may give more correct and safer answers than whole-course search or translation. If this holds on the larger, blind-graded test set, it might support a short paper.